CASE STUDY
RivalRadar
ByteDance CIS AI Full-Stack Project Challenge · Outstanding Project Award
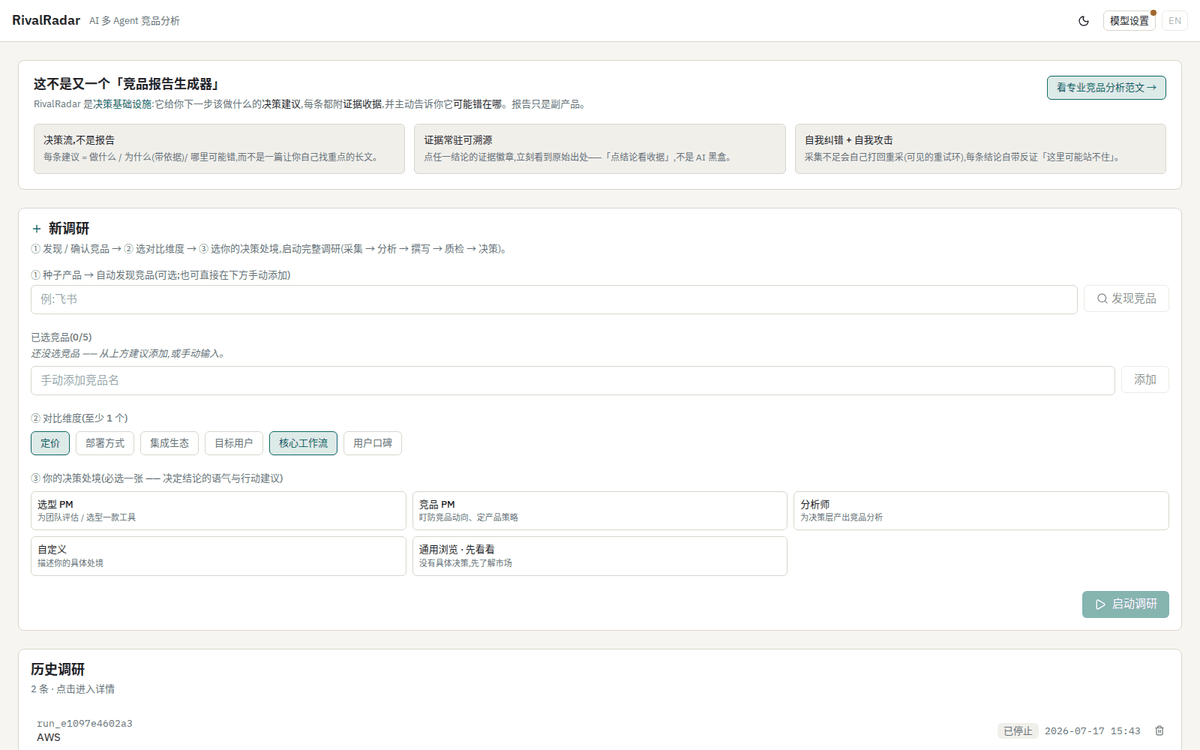
Outstanding Project Award, ByteDance CIS AI Full-Stack Project Challenge. Solo full-stack, core version in three weeks. Turns competitive research from a black-box long report into a reviewable decision process where every conclusion traces back to its evidence
Background
Three chronic problems in PM competitive research: scattered sources, inconsistent comparison criteria, and unverifiable AI conclusions. A report with links doesn’t mean the sources actually support it, and users still open every page to hunt for the evidence line by line. AI-generated competitive reports look finished, but the conclusions can’t be traced back to sources and the research process stays invisible, so product managers won’t make decisions on them directly. The category had to change, from a report generator to reviewable decision support.
Judgment
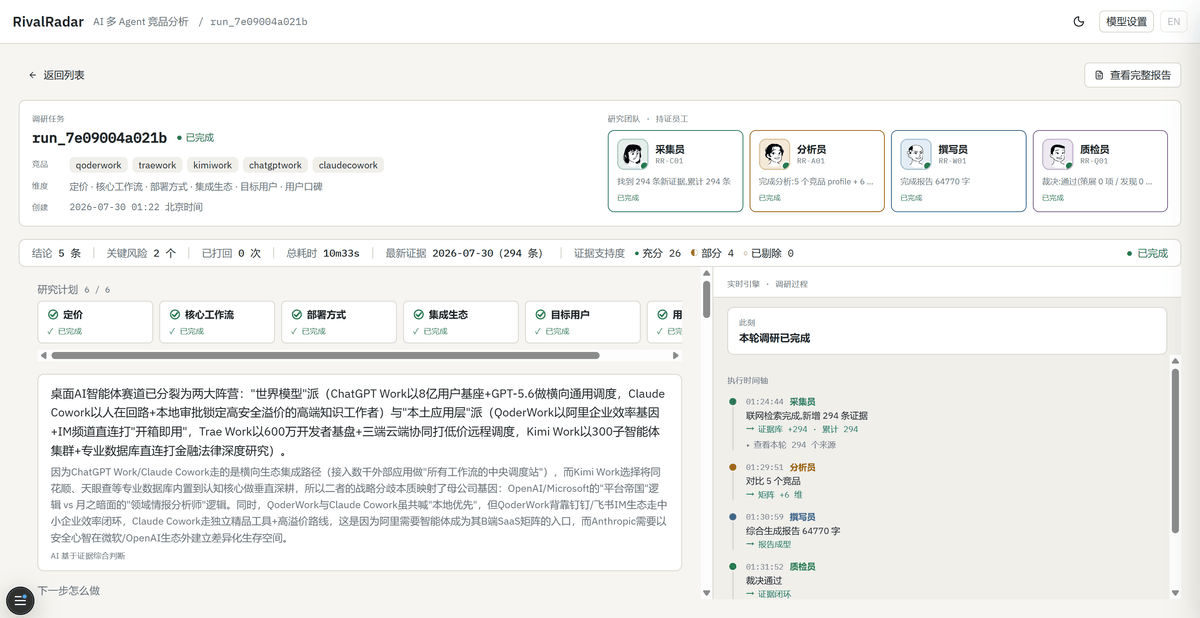
- Decomposition standard: a single model emitting a long report is opaque and hard to debug. I split the work into 4 specialized agents (collector, analyst, writer, QC) by “independent goal, inspectable artifact, separate rework path,” orchestrated with LangGraph into a
collect → analyze → write → QC → decide → finalizeloop, with QC failures routed back by gap type - Conclusion gating: “links attached” upgraded to a system-level invariant. Every comparison cell and decision must bind a source plus the exact quoted sentence. A rule gate checks citation existence, dimension legality, and evidence coverage; an LLM then judges each claim as fully / partially / unsupported: unsupported claims are dropped, partial ones get boundary labels, missing evidence triggers bounded re-collection, and persistent gaps are shown as explicit blanks, never a hard-coded answer
- Flipping QC’s role: the first QC could only reject a run wholesale, and it once misjudged a nearly complete matrix as insufficient data. I redesigned it as graded handling: missing evidence routes back to collection for targeted re-collection, structural problems route back to analysis for restructuring, conclusions that can’t hold up are dropped and left blank, and the confidence state of every conclusion is shown to the user
- Process as trust: trust in agent products comes from transparency, not pretty results. A live workbench streams queries, sources, per-cell verification, and self-correction loops; the whole run replays faithfully after a page refresh
Actions
Solo full-stack, core version in three weeks for the competition (post-contest iterations excluded from the award narrative): FastAPI + LangGraph + SQLite/Postgres backend, React 19 frontend. The evaluation numbers were measured after the contest: on a 60-item conclusion-evidence evaluation set (20 items for each of the three support relations, constructed and labeled by me), evidence-support judgment reached 88.4% Macro-F1, unfounded-conclusion detection hit 90% on both Precision and Recall, and the human-review correction rate was 11.7%. Evaluation guides iteration rather than decorating the resume. Engineering discipline: degradation always visible, no silent error swallowing, an anti-platitude blacklist. 402 tests across 44 test files, all green in about 13 seconds.
Results
- Outstanding Project Award, ByteDance CIS AI Full-Stack Project Challenge; the live version covers the full loop: competitor discovery → source collection → structured comparison → decision suggestions → evidence trace-back
- Stated limits (honesty matters): semantic verification has coverage boundaries, covering comparison cells and decisions but not all free text; LLM verdicts prove the entailment between conclusion and evidence, not the conclusion’s objective correctness, so whether a conclusion is actually right still comes down to human judgment